lastdevops / infrastructuretaking new projects
Production infrastructure, built and run by senior engineers
We design, migrate and operate Kubernetes platforms, CI/CD and observability, make sure they survive a lost data center, and stay on call 24/7 once you're live. Three co-founders, all hands-on — no account managers between you and the people doing the work.
An engineer replies, not a salesperson — within one business day.
- Building container platforms since 2014
- 24/7 on-call
- Everything as code in your Git
- Co-founders do the work
Official cloud partners
- Yandex Cloud
- Selectel
- Timeweb Cloud
symptoms.log
Sound familiar?
Deploys depend on one person
Nobody else knows how the pipeline really works, and that person wants a vacation.
Alerts fire at night and nobody owns them
Developers are on call by accident, and real incidents get lost in the noise.
Backups nobody has restored
They run every night, but nobody knows how long a full recovery would take — or if it works.
The AI pilot is stuck in a notebook
It worked in a demo, and there is no path to a secure, monitored production service.
services/
One team for the whole lifecycle
We build the platform, keep it running, make sure it recovers — and connect AI and custom software to it.
Build and run
- DevOps as a ServiceA senior DevOps team on a monthly retainer: CI/CD, Kubernetes, IaC and observability, built in your repos and run with you. Start with a 3–5 day audit.
- SRE as a Service with 24/7 on-callManaged SRE with 24/7 on-call, SLOs, incident response and written postmortems. Engineers who know your systems take the pager, not a call centre.
- Kubernetes consulting and supportKubernetes design, migration, upgrades and 24/7 support on cloud, bare metal and air-gapped sites, from engineers who have built orchestrators since 2014.
- Infrastructure audit in 3–5 daysA fixed-scope review of reliability, security, delivery, backups and cost. A written report with prioritized risks and a plan — yours to keep.
Resilience
- High availability architectureRemove single points of failure: multi-zone clusters, database failover, zero-downtime deploys and load testing, designed against your real uptime target.
- Backup and disaster recoveryBackups you have actually restored. DR plans with clear RPO and RTO, scheduled restore drills and runbooks for Kubernetes, databases and cloud accounts.
- Multi-cloud and hybrid infrastructureRun across clouds, regions and your own hardware without doubling the work: portable Kubernetes, Terraform and GitOps, with failover where it pays off.
Build on top
- AI integration for products and business processesBring LLMs into your products and workflows: RAG, agents and private model deployment, run with the same engineering, security and on-call as your core stack.
- Custom software developmentBackend services, internal tools and platforms in Go, Python and Node.js with React front ends, shipped with CI/CD, observability and infrastructure built in.
pipeline.yml
How we work
Four stages with a clear outcome at each. After every stage you decide whether to go further.
We map what you have today: services, dependencies, bottlenecks, risks and real costs.
- inventoryInventory of services, data and external integrations
- dependenciesDependency map and components that must never stop
- cost-reviewCurrent running costs and where money leaks
- risk-reportRisks: single points of failure, backups, access, security
Outcome: A report with the current state and a prioritized list of problems
what-you-keep.md
What you keep, in every engagement
- Infrastructure as code in your repository
- A runbook for every alert we page on
- Dashboards and SLOs you can read without us
- Architecture docs and a decision log
- A handover plan if you ever take it in-house
Last.Backend: a way to production for AI agents
Built by our co-founder. Agents run in isolated microVMs, permissions and network access are set by policy, and production needs a human to approve.
- ai-agents
- microvm
- policy-as-code
- mcp
- apache-2.0
TEAM.md
Who will work on your project
There are three of us, by design: the engineers you talk to are the engineers who do the work. No account managers, no hand-offs.
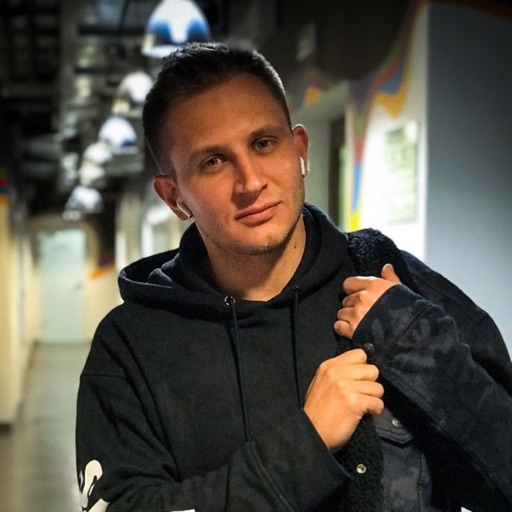
Alexander Kaloshin
Co-founder
20+ years in IT. In 2014 he founded Last.Backend, a container orchestrator built at almost the same time as Kubernetes. Leads our AI practice.
- Last.Backend: isolated runtimes and a way to production for AI agents
- Fault-tolerant infrastructure: Kubernetes, CI/CD, bare metal
- Go engineering
- Speaker at ProIT Fest and GolangConf
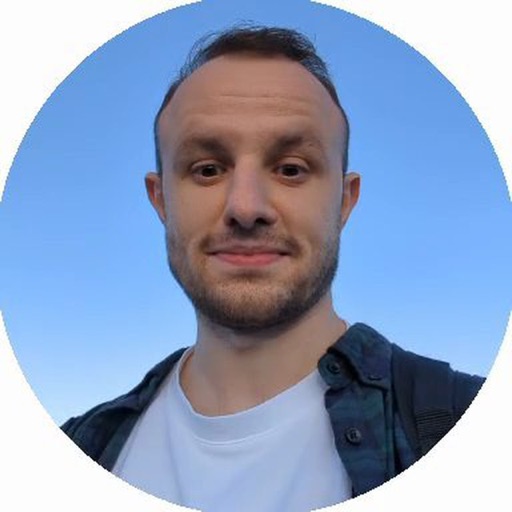
Alexander Tikhomirov
Co-founder
7 years in DevOps and dozens of delivered projects, from a first pipeline to production under heavy load.
- Infrastructure design and operations
- Cloud migrations and greenfield builds
- CI/CD, Kubernetes, infrastructure as code
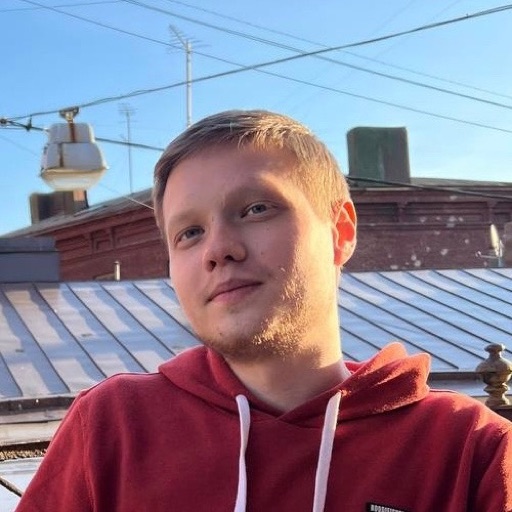
Denis Gerasimov
Co-founder
5 years in DevOps. Takes on the hardest problems and sees them through.
- Complex infrastructure projects
- Monitoring, on-call and incident response
- Operations automation
remote.md
Working with us from abroad
UTC+3, on call 24/7
One to two hours ahead of Central Europe, so our working days overlap almost completely. For US teams we meet in your morning and cover your night.
Least-privilege access
Accounts you create for us, MFA, logged access you can revoke at any time. NDA before the first technical call if you prefer.
Nothing locked with us
Code, infrastructure and documentation live in your repositories from day one, and cloud accounts stay in your name.
FAQ.md
FAQ
- Who will actually work on our infrastructure?
- One of our three co-founders leads every engagement and stays on it. The engineers you meet on the first call are the ones with access to your systems and the ones who answer pages.
- Where is your team, and what hours do you work?
- We work in UTC+3. That is one to two hours ahead of Central Europe, so a European business day overlaps almost entirely with ours. For US teams we schedule calls in your morning. Incidents are covered 24/7.
- How do we start?
- With a fixed-scope audit: 3–5 days, a written report and a prioritized plan. The report is yours whether or not you continue with us.
- Do we own everything you build?
- Yes. Code, Terraform, Helm charts and runbooks live in your repositories from day one.
- Do you replace our in-house team?
- No, unless you want us to. We usually work alongside your developers: we own the platform and on-call, they own the product.
Start with a 3–5 day audit
We'll map your infrastructure, rank the risks and give you a plan. The report is yours to keep.